7 Neural Networks
Neural networks are a very versatile set of models to make predictions. In this section we discuss their basic working. We start with a network with a single neuron. Then we extend to sets of neurons stacked vertically into layers, then placed horizontally side by side within a layer. We show how to use gradient descent of Section 5.1 to update the parameters of the network to fit the training data. We present different types of ideas and mechanisms that are used to set up and regularize neural networks. How to engineer a good architecture is a hot topic in current research.
We remark that we only discuss how neural networks work, but not why. Their power can perhaps best be understood as an emergent phenomenon.1A simple example of an emergent phenomenon is the freezing of water. Clearly, one molecule of H2 O is not water, but how many molecules are needed before it becomes a water droplet that can freeze? Similarly, one biological neuron cannot think. Put many together and we obtain the brain of a snail. Put a huge number together and we get a rat that can solve labyrinth puzzles, with yet more we have ’us’.
7.1 Single-neuron networks
The simplest neural network consists of a single neuron taking a single feature \(x\) as input and producing one prediction \(\hat y\). Fig. 7.1 shows the two steps. It does this by first computing the logit (5.1.3)
\begin{align*} z = ax+b, \end{align*}with two parameters \(a\) and \(b\). Then it applies an activation function to obtain the output \(\hat y \in \Yset\). Throughout this chapter we use the sigmoid as example,
\begin{align*} \hat y = \sigma(z), \qquad \sigma(z) = \rb{1+e^{-z}}^{-1}. \end{align*}The role of \(\sigma\) is to transform the unbounded logit \(z\in\R\) into a number between \(0\) and \(1\), so that \(\hat y\) can be interpreted as a probability. Thus, once \(a\) and \(b\) are known, prediction is just the calculation above. Note that the mechanism we describe below can be easily changed to other activiation functions.
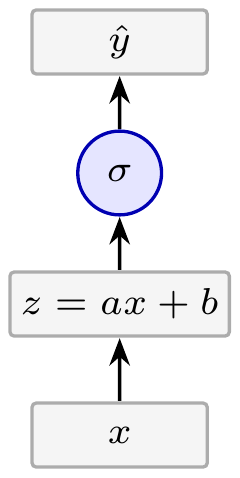
Figure 7.1: A single neuron computes a logit \(z\) from the input \(x\) and passes it through the activation function \(\sigma\) to obtain the response \(\hat y\).
For training we use the observations \((x,y)\) in the training set \(\Tset\). The goal is to solve the problem:
\begin{align*} \theta^{*} &\in \argmin_{\theta} \hat R_{\Tset}(a,b), & \theta &= (a,b), \tag{7.1.1} \end{align*}where the training risk is the average over the training samples,
\begin{align*} \hat R_{\Tset}(a,b) &= \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\lscr(y, z), & z&=ax+b, \end{align*}and \(\lscr(y, z)\) is the loss of the parameters \((a,b)\) on the single training sample \((x,y)\). Below we use squared-error loss \(\lscr(a,b;x,y) = \rb{y - \hat y}^{2}= \rb{y - a x -b}^{2} \). For hard labels \(y\in\set{0,1}\) the binary cross-entropy (5.1.5) is the natural choice for \(\lscr\), and for soft targets \(y\in[0,1]\).
The solution \(\theta^{*} = (a^*, b^*)\) can be found with the gradient descent tools of Section 5.1. Once solved, \(\theta^*\) is then used for prediction: for a new predictor \(x\), the neuron returns \(\sigma(a^* x + b^*)\) as the prediction.
Regularization is important even for this single neuron network; however, these ideas apply more generally.
Early stopping uses a validation set to decide when to stop training. Split the available labeled data into a training set \(\Tset\) and a validation set \(\Vset\). The parameters are updated by gradient descent on \(\hat R_{\Tset}\) as before, but now, at each iteration \(k\), we store the validation risk
\begin{align*} \hat R_{\Vset}(\theta^{(k)}) = \frac{1}{|\Vset|}\sum_{(x,y)\in\Vset}\lscr(\theta^{(k)};x,y) \end{align*}together with the parameters \(\theta^{(k)}=(a^{(k)},b^{(k)})\). We continue training as long as the trainging and validation loss decrease. When the validation risk has failed to improve for a number of successive iterations, we stop iterating and use
\begin{align*} k^* \in \argmin_k \hat R_{\Vset}(\theta^{(k)}) \end{align*}to select \(\theta^{(k^*)}\) as the fitted parameter vector for prediction instead of the last parameter values obtained from training. This matters because the training risk can keep decreasing, while the validation risk can increase once the model begins to fit accidental details of \(\Tset\).
Weight decay copies the idea from ridge regression by including a penalty in the objective:
\begin{align*} \min_{a,b}\hat R_{\Tset,\lambda}(a,b), \qquad \hat R_{\Tset,\lambda}(a,b) = \hat R_{\Tset}(a,b) + \frac{\lambda}{2}a^2, \end{align*}where \(\lambda\geq 0\) is a tuning parameter.2In larger networks, the weight \(a\) is a matrix. Then we penalize the sum of the squared entries of the weight matrix, \(\norm{A}^2\), instead of just \(a^2\).
The bias \(b\) is often left out of the penalty. The reason is that \(a\) controls the steepness of \(\sigma(ax+b)\), while \(b\) controls where the steep part of the curve lies.3\(ax+b=0\) at \(x=-b/a\). Penalizing \(a\) discourages overly sharp changes in the fitted probabilities. Penalizing \(b\) would also discourage moving the steep part of the curve to where the data place it, which is usually not the intended effect.
The extra term in the objective contributes \(\lambda a\) to the derivative with respect to \(a\), so the update in gradient descent contains a small shrinkage toward zero. As \(\frac{\partial}{\partial a}\hat R_{\Tset,\lambda}(a,b)=\frac{\partial}{\partial a}\hat R_{\Tset}(a,b)+\lambda a\), the update for \(a\) is
\begin{align*} a^{(k+1)} &= a^{(k)} -\eta\left( \frac{\partial}{\partial a}\hat R_{\Tset}(a^{(k)},b^{(k)}) +\lambda a^{(k)} \right)\\ &= (1-\eta\lambda)a^{(k)} -\eta\frac{\partial}{\partial a}\hat R_{\Tset}(a^{(k)},b^{(k)}). \end{align*}The first term is a shrunken version of the old value \(a^{(k)}\), before the usual gradient of the training risk is added. Note that \(\lambda\) should be chosen with care: the minimal requirement is \(|1-\eta\lambda|<1\).
7.2 Multi-neuron networks
A single neuron only gives shifted and stretched copies of one fixed nonlinearity, \(\sigma(ax+b)\). Neural networks become more flexible by combining many such transformations: some are placed in a sequence of layers, making the network deeper, and some are placed side by side, making a layer wider. Networks built from multiple layers, each of several neurons wide, are called multilayer perceptrons.
Making networks deeper and wider can improve prediction quality. Different hidden neurons can learn different useful patterns in the input, and later layers can combine patterns learned by earlier layers. However, if the network is made too large for the amount of data, the same flexibility can overfit by picking up accidental noise instead of structure.
We first study depth in the simplest case: a scalar stack with one neuron per layer. Then we make the network wider, and introduce more indices to cope with the extra complexity.
The simplest stack passes information from single neurons from one layer to the next, see Fig. 7.2. For instance, starting from the input \(x\), define
\begin{equation*} \begin{aligned} z_1 &= a_1x+b_1, & h_1 &= \phi_1(z_1),\\ z_2 &= a_2h_1+b_2, & h_2 &= \phi_2(z_2),\\ z_3 &= a_3h_2+b_3, & \hat y &= \sigma(z_3). \end{aligned} \tag{7.2.1} \end{equation*}Each \(a_i\) and \(b_i\), for \(i=1,2,3\), is a trainable parameter; \(\phi_1\) and \(\phi_2\) are activation functions, in the same role as \(\sigma\).4We discuss examples below. The intermediate values \(h_1\) and \(h_2\) are called hidden as the network only uses them internally. The \(z_i\) are the pre-activations; the last one, \(z_3\), is the logit. Since the signal flows only forward, from \(x\) through \(h_1\) and \(h_2\) to \(\hat y\), without cycles or feedback, such a network is called feedforward.
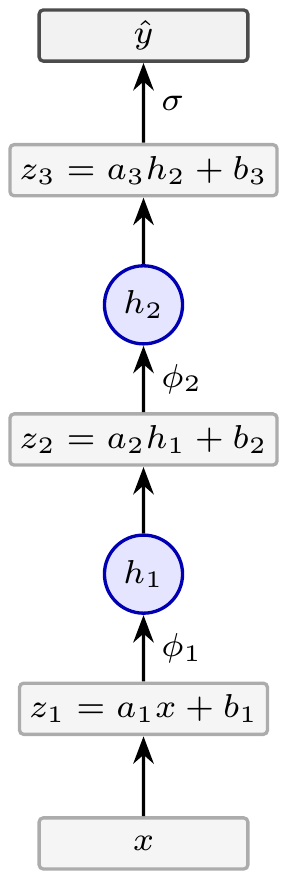
Figure 7.2: A scalar multilayer network.
This stack is richer than a single neuron because each layer transforms the signal once more, so a later layer works with features produced by the earlier layers rather than with the raw input.
Prediction is implemented as a forward pass. Given parameters \((a_i, b_i)\) for each neuron, compute for the predictor \(x\) the preactivations \(z_1, h_1, z_2, h_2, z_3\) in order of (7.2.1) and return \(\hat y=\sigma(z_3)\).
Training minimizes the training risk by (mini-batch) gradient descent, now over all six parameters \(\theta=(a_1,b_1,a_2,b_2,a_3,b_3)\). The new difficulty is computing the gradient. Backpropagation5Michael A. Nielsen, Neural Networks and Deep Learning is the systematic way to handle this: it is the chain rule, applied from the output back to the input.
First, apply a forward pass to one observation \((x,y)\) to compute the loss \(\lscr=\lscr(y, \hat y)\), all pre-activations \(z_i\) and all hidden values \(h_i\). The computations below use these values.
Backpropagation starts at the output, that is, at the top of Fig. 7.2. Since \(\hat y=\sigma(z_3)\), the chain rule applied to the squared loss \(\lscr=(y-\hat y)^2/2\) gives
\begin{align*} \delta_{3} = \frac{\partial \lscr}{\partial z_3} = \frac{\partial \lscr}{\partial \hat y} \frac{\partial \hat y}{\partial z_3} = \frac{\partial \lscr}{\partial \hat y}\sigma'(z_3) = \rb{\hat y-y}\,\hat y(1-\hat y), \tag{7.2.2} \end{align*}i.e., the factor we met in the one-neuron network. The parameters \(a_3\) and \(b_3\) enter the loss only through \(z_3=a_3h_2+b_3\), so again by the chain rule,
\begin{align*} \frac{\partial \lscr}{\partial a_3} &= \frac{\partial \lscr}{\partial z_3} \frac{\partial z_3}{\partial a_3} = \delta_3 h_2, & \frac{\partial \lscr}{\partial b_3} &= \frac{\partial \lscr}{\partial z_3} \frac{\partial z_3}{\partial b_3} = \delta_3. \end{align*}Note that from the forward pass we have the numerical values of \(\delta_3\) and \(h_2\) at the given sample \((x,y)\). Thus, the RHSs are just numbers that we6That is, the computer. can compute.
Now step one layer back. From (7.2.1) and the chain rule
\begin{align*} \delta_{2} &=\frac{\partial \lscr}{\partial z_2} = \frac{\partial \lscr}{\partial z_3} \frac{\partial z_3}{\partial h_2} \frac{\partial h_2}{\partial z_2} = \delta_3\, a_3\, \phi_2'(z_2). \end{align*}Since \(z_2=a_2h_1+b_2\), again by the chain rule,
\begin{align*} \frac{\partial \lscr}{\partial a_2} &= \frac{\partial \lscr}{\partial z_2} \frac{\partial z_2}{\partial a_2} = \delta_2 h_1, & \frac{\partial \lscr}{\partial b_2} &= \frac{\partial \lscr}{\partial z_2} \frac{\partial z_2}{\partial b_2} = \delta_2. \end{align*}One more step of the same kind yields
\begin{align*} \delta_1 &= \delta_2\, a_2\, \phi_1'(z_1), & \frac{\partial \lscr}{\partial a_1} &= \delta_1 x, & \frac{\partial \lscr}{\partial b_1} &= \delta_1. \tag{7.2.3} \end{align*}Note the pattern: One forward pass computes the \(z_i\) and hidden values \(h_i\), one backward computes each \(\delta_i\) from \(\delta_{i+1}\) by multiplying with the weight \(a_{i+1}\) and the local slope \(\phi_i'(z_i)\). Together they deliver the complete gradient \(\nabla\lscr(\theta;x,y)\) for the given sample \((x,y)\).
The parameter update is then the same as before, except that rather than updating from just one sample, we use a mini-batch \(\Bset\) to estimate the gradient with (5.1.6) and update the parameters through: \[ \theta^{(k+1)} = \theta^{(k)} - \eta\, \nabla\hat R_{\Bset}(\theta^{(k)}). \] For instance, if the mini-batch would consist of one sample, then,
\begin{align*} a^{(k+1)}_{1} &= a^{(k)}_{1} - \eta \frac{\partial \lscr}{\partial a_1} = a^{(k)}_{1} - \eta \delta_1 x, & b^{(k+1)}_{1} &= b^{(k)}_{1} - \eta \frac{\partial \lscr}{\partial b_1} = b^{(k)}_{1} - \eta \delta_1. \end{align*}The other parameters follow in the same way.
Because the training risk of a neural network is not necessarily convex, two runs started from different initial parameter values may end at different local minima. A simple practical response is to train the same architecture from several random initializations and keep the run with the lowest validation risk.
Generalizing to networks with \(L\) layers is straightforward.
Widening a layer places several neurons side by side in one layer, see Fig. 7.3. A neuron in a wide layer now receives several inputs, one from every neuron in the previous layer, so its weights carry three indices: \(A_i(j,k)\) is the weight that neuron \(j\) of layer \(i\) applies to its \(k\)-th input. Then hidden layer \(i\) computes the components of its pre-activation and hidden vector as
\begin{align*} z_i(j)&=\sum_{k=1}^{q_{i-1}} A_i(j,k)h_{i-1}(k) + b_i(j), & h_i(j) &= \phi(z_i(j)). \tag{7.2.4} \end{align*}Collecting the weights of layer \(i\) in the matrix \(A_i\in\R^{q_i\times q_{i-1}}\), whose \((j,k)\) entry is \(A_i(j,k)\), the hidden vector \(h_{i-1}\in \R^{q_{i-1}}\), and the biases in the vector \(b_i\in\R^{q_i}\), this becomes
\begin{align*} z_i &= A_i h_{i-1} + b_i, & h_i &=\phi(z_i), & i&=1,\ldots,L, \tag{7.2.5} \end{align*}where \(\phi\) is applied element-wise. The output is layer \(L+1\). It consists of one neuron, so \(q_{L+1}=1\), and it reads the last hidden layer,
\begin{align*} z_{L+1} &= A_{L+1}h_L + b_{L+1}, & \hat y &= \sigma(z_{L+1}) \tag{7.2.6} \end{align*}with \(A_{L+1}\in\R^{1\times q_L}\) and \(b_{L+1}\in\R\). Thus the output layer has the same form as a hidden layer; only its activation differs, \(\sigma\) instead of \(\phi\).
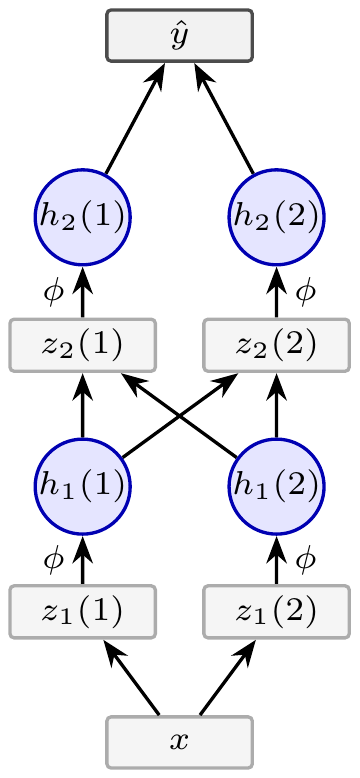
Figure 7.3: A small multilayer perceptron.
Each layer has its own parameters \(A_i(j,k), b_i(j)\); thus \[ \theta=(A_1,b_1,\ldots,A_{L+1},b_{L+1}). \] Note how quickly \(\theta\) grows: layer \(l\) alone has \(q_l(q_{l-1}+1)\) parameters.
Including multiple features is now straightforward. When the input is a feature vector \(x\in\R^p\), just set \(h_0=x\) and \(q_0=p\), and all of (7.2.5) applies right away. Thus, moving from one to \(p\) features changes only the bookkeeping for the first layer, later layers are unaffected as they read only from the previous hidden layer.
Backpropagation carries over nearly unchanged. Again, there is one \(\delta\) per neuron, so \(\delta_i\in\R^{q_i}\) is a vector. The output layer \(L+1\) has one neuron, so for squared loss
\begin{align*} \delta_{L+1} = \rb{\hat y - y}\,\hat y(1-\hat y). \end{align*}From this, the other backward recursion become with the chain rule,
\begin{align*} \delta_i(j) &= \frac{\partial \lscr}{\partial z_i(j)} = \sum_{k}\frac{\partial \lscr}{\partial z_{i+1}(k)} \frac{\partial z_{i+1}(k)}{\partial h_i(j)} \frac{\partial h_i(j)}{\partial z_i(j)} \\ &= \sum_{k} \delta_{i+1}(k) A_{i+1}(k,j) \phi_i'(z_i(j)), \end{align*}where we use (7.2.4) for the second partial derivative and \(h_i(j) = \phi_i(z_i(j))\) for the third. Now note that the summation over \(k\) is the multiplication of the vector \(\delta_{i+1}\) and the matrix \(A_{i+1}\). With the Hadamard product7The Hadamard product, written as \(C = A \odot B\), of two matrices \(A\) and \(B\) with the same dimensions is the element-wise multiplication: \(C_{ij} = A_{ij} B_{ij}\). we can then write
\begin{align*} \delta_i = \rb{\delta_{i+1} A_{i+1}} \odot \phi_i'(z_i), \qquad i = L,\ldots,1. \end{align*}Finally, the gradients of layer \(i=1,\ldots,L+1\) become
\begin{align*} \frac{\partial \lscr}{\partial A_i} &= \delta_i\, h_{i-1}^{\top}, & \frac{\partial \lscr}{\partial b_i} &= \delta_i, \end{align*}because
\begin{align*} \frac{\partial \lscr}{\partial A_i(j,k)} = \frac{\partial \lscr}{\partial z_i(j)} \frac{\partial z_i(j)}{\partial A_i(j,k)}= \delta_i(j) h_{i-1}(k). \end{align*}As an aside, in software these formulas need not be derived by hand: automatic differentiation records every elementary operation of the forward pass and applies the chain rule mechanically in reverse, which reproduces exactly the backpropagation computation above, for a network of any shape. This is what allows practitioners to change an architecture without redoing any calculus. Also, in real large networks, plain gradient descent is often replaced by specialized optimizers such as momentum methods, Adam, or AdamW.8Wikipedia: Stochastic gradient descent, Adam.
Multi-neuron networks can use other regularization techniques besides early stopping and weight decay.
Dropout is a technique that aims to prevent the network from relying too much on just a few neurons in a layer. The risk with \(q\) parallel neurons is that during training they can start to cooperate too closely so that just a few neurons in that layer become dominant, which in turn may lead to tuning that layer to accidental details of the training set. Dropout counters this by switching off some neurons randomly selected for each mini-batch update, see Fig. 7.4. Like this, the network cannot rely on just a few neurons; in that sense, it should make networks more robust.
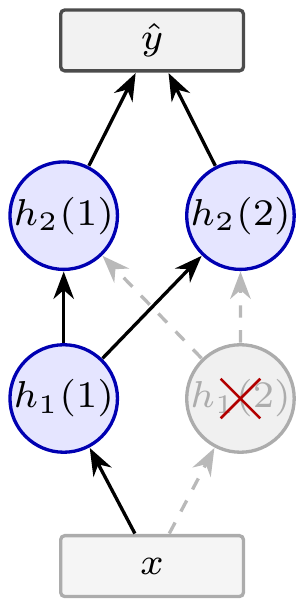
Figure 7.4: Dropout switches off hidden units during training.
Dropout is generally applied to each hidden layer separately; we discuss the details for one layer. Given the vector \(h_i\) of hidden layer \(i\), let \(\rho\in[0,1)\) be the dropout probability. For each mini-batch update, take \(M_i=(M_i(1),\ldots,M_i(q_i))\) where
\begin{align*} M_i(j)\sim \Bern{1-\rho}, \quad j=1,\ldots,q_i \end{align*}are independent mask variables.9In deeper networks, use a separate mask for each dropout layer. Then, replace \(h_i\) by its randomly thinned version
\begin{align*} \tilde h_i = \frac{M_i\odot h_i}{1-\rho}, \end{align*}and use \(\tilde h_i\) instead of \(h_i\) in (7.2.5). Like this, each (mini-batch) update trains a differently thinned network. Since the model cannot rely on the same hidden units always being present, no single neuron can play too dominant a role.
The division by \(1-\rho\) is called inverted dropout. It keeps \(\E{\tilde h_i(j)}=h_i(j)\), so that in expectation, the activation remains equally strong during each training step.
Dropout is only applied during training. Once trained, the full network is used for prediction.
DropConnect is the same idea applied to individual weights instead of hidden units. For the weight matrix \(A_i\), take a mask matrix \(B_i\) of the same shape, with independent entries
\begin{align*} B_i(j,k)\sim \Bern{1-\rho}. \end{align*}During training, replace \(A_i\) by its randomly thinned version
\begin{align*} \tilde A_i = \frac{B_i\odot A_i}{1-\rho}. \end{align*}As with dropout, the random masking is only used during training; once trained, the full weight matrix is used for prediction.
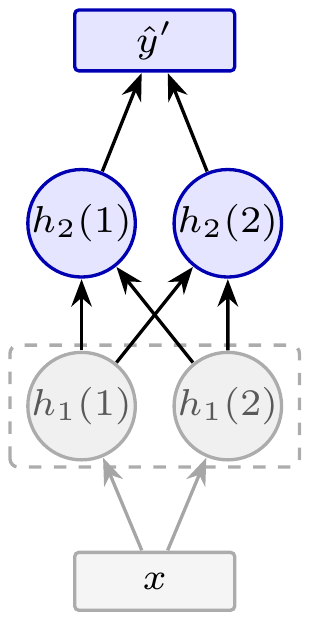
Figure 7.5: Freezing one layer keeps its weights fixed while the rest of the network trains.
Freezing10Wikipedia: Fine-tuning (deep learning). keeps selected parameters fixed during training, as in Fig. 7.5. The frozen neurons still compute their values in the forward pass, but their parameters are excluded from the gradient updates. This is a deliberate restriction on what the optimizer is allowed to change.
Freezing is a useful technique to enable transfer learning11Freezing is not the same as transfer learning; it is one common tool used when reusing a pretrained network for a new task.. Transfer learning is to reuse part of a network trained on one task for a related new task. A typical workflow is:
- Start from a network already trained on a large source data set.
- Keep its lower layers, because they often capture generic features.
- Add (or replace) an output layer for the new task.
- Train only this last layer.
- Optionally unfreeze some of the lower layers and continue training with small learning rate. This is known as fine-tune it.
Thus, by freezing the lower layers we can save computation and protect against overfitting when the new data set is small.
7.3 Further architecturial aspects
Except specifying the number of layers and the widths of the layers, there are some other parts of a neural networks that need consideration: which activation functions to use, how many outputs the network should produce, and how information should flow12That is, how the neurons and the layers are connected. between distant parts of the network.
A first question is what a given architecture can represent at all. The universal approximation theorem13Wikipedia: Universal approximation theorem. given an intereting answer: a one layer network that is sufficiently suffices in the following sense. Take \(L=1\) and the last activation the identity so that network computes \[ \hat f(x) = \sum_{j=1}^{q_1} A_2(1,j)\, \sigma\rb{\sum_{k=1}^{p} A_1(j,k)\,x(k) + b_1(j)} + b_2, \] i.e., a weighted sum of \(q_1\) shifted and stretched copies of the sigmoid function. The theorem says that for every continuous \(f\) on a compact domain and every \(\epsilon>0\) there are a width \(q_1\) and parameters \(A_1,b_1,A_2,b_2\) such that \(|\hat f(x)-f(x)|<\epsilon\) for all \(x\) in that domain. Thus, one hidden layer suffices, provided it is wide enough
This is an existence result, not a training guarantee. So the interesting question is not whether an architecture can represent a function, but which architectures reach a given accuracy with few parameters and can still be trained; this is the subject of current research.
Activation functions need not be sigmoid. Another common hidden-layer choice is the ReLU,14Wikipedia: Rectified linear unit.
\begin{align*} \phi(z)&=\max\set{0,z} & \phi'(0) &=0. \end{align*}This is useful because an active15That is, when \(z>0\). ReLU has derivative \(1\): it passes the gradient backward without shrinking it. A sigmoid hidden unit, by contrast, has derivative at most16\(\sigma'(z)=\sigma(z)\rb{1-\sigma(z)}\leq 1/4\) \(1/4\) and becomes almost flat for large positive or negative \(z\) which leads to the following problem. Recall the backpropagation recursion applied to the simple three-layer feedforward network above. For instance, in example (7.2.2)--(7.2.3), we see that
\begin{align*} \delta_{1} = a_{2}\phi_{1}'(z_{1}) a_{3}\phi_{2}'(z_{2}) \frac{\partial \lscr}{\partial \hat y} \sigma'(z_{3}). \tag{7.3.1} \end{align*}Each extra layer contributes one more weight and one more slope. So in a stack of, say, \(15\) sigmoid layers the slopes alone contribute a factor of at most \((1/4)^{15}\approx 10^{-9}\). Thus, when using sigmoids throughout, the absolute value of gradient becomes small, and the lower layers barely learn; this is why stacks of more than a few layers are hard to train. This phenomenon is known as vanishing gradients.
ReLU does not suffer from this problem because its derivative is either 0 or 1.17The probability that a preactivation hits 0 is negligible.
A smooth variant of the ReLU is the GELU,18The Gaussian error linear unit, Wikipedia: Rectified linear unit, GELU. Is is used in GPT-style language models. \[ \phi(z)=z\,\P{Z\leq z},\qquad Z\sim\Norm{0,1}. \] For large positive \(z\) it behaves like the identity and for large negative \(z\) it tends to \(0\), as the ReLU does. It differs near the origin: the GELU is negative for every \(z<0\), with a minimum of about \(-0.17\) at \(z\approx-0.75\), so unlike the ReLU it is not monotone.
Output heads19Do not confuse these output heads with the attention heads used inside Transformer layers of large language models. are final output neurons, or final small output layers, for separate prediction tasks, see Fig. 7.6. So far, the network had just one output head: one \(\hat y\) for the input \(x\).] However, often we can ask several related questions about the same input. For instance, does a patient has illness A and illness B? Each such question can be answered by its own head but, as Fig. 7.6 shows, all heads share the same hidden layer.
For \(K\) such questions, take as logits and outputs
\begin{align*} z^{(r)} = b^{(r)}_{0} + \sum_{j=1}^{q_L} a^{(r)}(j) h_L(j), \qquad \hat y^{(r)} = \sigma(z^{(r)}), \qquad r=1,\ldots,K. \end{align*}Thus, each head has its own training parameters.
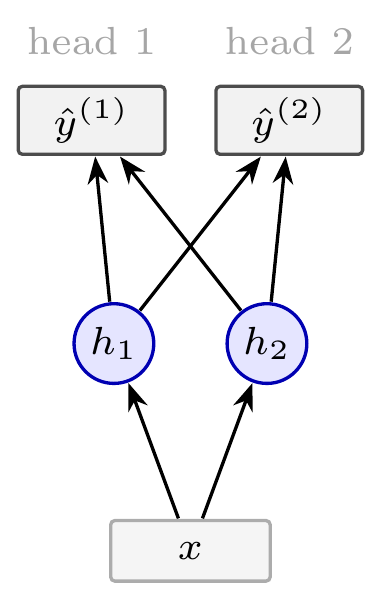
Figure 7.6: Each head is a separate output neuron reading the same hidden layer.
For training, this means that, instead of samples with an outcome \(y\), each observation has multiple targets \(y^{(1)},\ldots,y^{(K)}\), one for each supervised head. Training changes little: take as loss the sum of the \(K\) per-head losses and apply backpropagation as before.
Sharing information from lower layers is efficient: the features \(h_L(j)\) are learned once but used \(K\) times. Interestingly, training with multiple labels per input, known as multi-task learning, offers another advantage. The gradient of every head’s loss flows back into the same hidden layer, so each hidden neuron now receives \(K\) training signals instead of one. The hidden layers \(h_i\) must therefore capture structure that all \(K\) prediction tasks have in common and can therefore not specialize in accidental details of a single task. Multiple heads thus act as regularizers for one another.
Skip connections become important in deep networks. A skip connection lets a layer pass its input directly to a later layer. A residual connection20Wikipedia: Residual neural network. is the additive case of a skip connection: the skipped input and the learned update are merged by addition, not by a more general function. So, instead of setting \(h_i = \phi_i(z_i)\) as in (7.2.1), the hidden values are given by
\begin{align*} h_i = h_{i-1} + \phi_i(z_i), \qquad z_i = A_i h_{i-1}+b_i, \end{align*}equivalently, \(\Delta h_i := h_i-h_{i-1} = \phi_i(z_i)\). Thus, , instead of being replaced in the forward pass, layer \(i\) receives an update \(\Delta h_i\) on the hidden vector of the previous layer.21This is close to an Euler step for a differential equation, where a new state is the old state plus a small change.
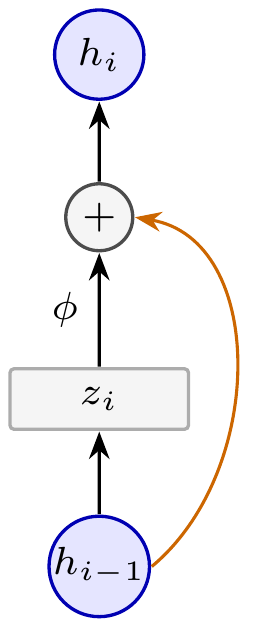
Figure 7.7: A residual connection sends a layer input directly to an addition node, where it is added to the layer update.
The effect of this change on training appears when we differentiate it: the derivative through the layer is
\begin{align*} \frac{\partial h_i}{\partial h_{i-1}} = I + \diag((\phi_i)'(z_i))A_i, \end{align*}and the identity matrix \(I\) is the point: the gradient always has a direct path back, so it no longer shrinks geometrically with depth, as it did in (7.3.1).
Residual connections help make networks of dozens or even hundreds of layers trainable. The first famous example was ResNet, an image-recognition network with residual blocks and over a hundred layers; the transformer blocks of large language models also wrap each sublayer in a residual connection.22Wikipedia: Residual neural network. Wikipedia: Transformer (deep learning architecture). Wikipedia: GPT-3. They also make each layer’s job easier: the layer only needs to learn a small correction to the identity map, not the whole transformation.
A skip connection need not skip just one layer. Examples include ResNet blocks, long U-Net connections, and DenseNet-style dense connections.23Wikipedia: Residual neural network, which also covers DenseNet. Wikipedia: U-Net. Yu, Wang, Shelhamer, and Darrell, Deep Layer Aggregation.
7.4 Exercises
What is a skip connection? Why are skip connections used in deep neural networks?
Solution
Solution, for real
See the main text. A skip connection passes a layer’s input directly to a later layer. They give information and gradients a direct path through the network, making deep networks easier to train.
What is dropout, and why is it used?
Solution
Solution, for real
Dropout randomly switches off neuron outputs during training. This reduces reliance on particular neurons and helps prevent overfitting.
What is DropConnect, and how does it differ from dropout?
Solution
Solution, for real
DropConnect randomly removes individual weights or connections, whereas dropout removes neuron outputs.
What does it mean to freeze a layer? Why can freezing be useful in transfer learning?
Solution
Solution, for real
Freezing a layer keeps its weights fixed while the remaining layers train. This allows pretrained features to be reused without changing them immediately.
What is early stopping, and how does it help prevent overfitting?
Solution
Solution, for real
Early stopping ends training when validation risk stops improving, before later updates overfit the training data.
What is weight decay, and what effect does it have on the fitted weights?
Solution
Solution, for real
Weight decay adds a penalty proportional to the squared size of the weights to the objective, encouraging smaller weights.
What is the vanishing-gradient problem?
Solution
Solution, for real
Gradients can become very small when propagated backwards through many layers, so early layers learn extremely slowly.
What is the difference between a residual connection and a general skip connection?
Solution
Solution, for real
A residual connection is an additive skip connection: the input is added to the learned update. A general skip connection may combine them in another way.
What is inverted dropout? Why use it?
Solution
Solution, for real
During training, surviving activations are divided by (1-ρ), so their expectation is unchanged and no rescaling is needed at prediction time.
What is fine-tuning in transfer learning?
Solution
Solution, for real
Fine-tuning continues training some previously pretrained layers, usually after first training a new prediction head, so the network adapts to the new task.
What is a multilayer perceptron?
Solution
Solution, for real
See the text.
Carry out backpropagation for the two-layer, single-neuron network \[ z_1=a_1x+b_1,\qquad h_1=\phi(z_1),\qquad z_2=a_2h_1+b_2,\qquad \hat y=\sigma(z_2), \] with squared loss \(\lscr=(y-\hat y)^2\). (Hint, derive the partial derivatives of \(\lscr\) with respect to \(a_1,b_1,a_2,b_2\), using the forward-pass values \(z_1,h_1,z_2,\hat y\).)
Solution
Solution, for real
Apply the chain rule from the output backwards. With \(\delta_2=\partial\lscr/\partial z_2\) and \(\delta_1=\partial\lscr/\partial z_1\), the result is
\[\begin{aligned} \delta_2 &= 2(\hat y-y)\sigma'(z_2), & \frac{\partial\lscr}{\partial a_2} &= \delta_2 h_1, & \frac{\partial\lscr}{\partial b_2} &= \delta_2,\\ \delta_1 &= \delta_2 a_2\phi'(z_1), & \frac{\partial\lscr}{\partial a_1} &= \delta_1 x, & \frac{\partial\lscr}{\partial b_1} &= \delta_1. \end{aligned}\]
Carry out backpropagation for the two-layer, single-neuron network \[ z_1=a_1x+b_1,\qquad h_1=\phi(z_1),\qquad z_2=a_2h_1+b_2,\qquad \hat y=\sigma(z_2), \] with the binary cross-entropy (5.1.5) as loss, \[ \lscr = -y\log\hat y-(1-y)\log(1-\hat y). \]
Solution
Solution, for real
Differentiating the loss with respect to \(\hat y\), \[ \frac{\partial\lscr}{\partial\hat y} = -\frac{y}{\hat y}+\frac{1-y}{1-\hat y} = \frac{\hat y-y}{\hat y(1-\hat y)}. \] Since \(\sigma'(z_2)=\hat y(1-\hat y)\), the two factors cancel: \[\begin{aligned} \delta_2 &= \frac{\partial\lscr}{\partial\hat y}\sigma'(z_2) = \hat y-y, & \frac{\partial\lscr}{\partial a_2} &= \delta_2 h_1, & \frac{\partial\lscr}{\partial b_2} &= \delta_2,\\ \delta_1 &= \delta_2 a_2\phi'(z_1), & \frac{\partial\lscr}{\partial a_1} &= \delta_1 x, & \frac{\partial\lscr}{\partial b_1} &= \delta_1. \end{aligned}\]
Carry out backpropagation for the two-layer, single-neuron network with a ReLU hidden activation and the identity as output activation, \(\phi_2(z)=z\) and squared loss, so that \[ z_1=a_1x+b_1,\qquad h_1=\text{ReLU}(z_1),\qquad \hat y=z_2=a_2h_1+b_2. \]
In what part of \(\Xset=\R\) are the network parameters updated? Where not?
What check should you do on the training set \(\Tset\) to prevent problems?
Solution
Solution, for real
Since \(\phi_2\) is the identity, \(\partial\hat y/\partial z_2=1\), and \[\begin{aligned} \delta_2 &= 2(\hat y-y), & \frac{\partial\lscr}{\partial a_2} &= \delta_2 h_1, & \frac{\partial\lscr}{\partial b_2} &= \delta_2,\\ \delta_1 &= \delta_2\,a_2\,\1{z_1>0}, & \frac{\partial\lscr}{\partial a_1} &= \delta_1 x, & \frac{\partial\lscr}{\partial b_1} &= \delta_1. \end{aligned}\] The ReLU derivative is \(\1{z_1>0}\), which is not defined at \(z_1=0\); the convention \(\phi'(0)=0\) settles that case.
At a sample with \(z_1\leq 0\) we have \(h_1=0\) and \(\delta_1=0\), so \(\partial\lscr/\partial a_1=\partial\lscr/\partial b_1= \partial\lscr/\partial a_2=0\). Only \(b_2\) is updated.
If \(z_1\leq 0\) for every sample in \(\Tset\), then \(a_1\) and \(b_1\) never change, so \(z_1\) stays negative for all samples and the hidden neuron is permanently stuck at \(0\). This is the dead ReLU.
The backward recursion of a network with \(L\) hidden layers of widths \(q_1,\ldots,q_L\) and a one-neuron output layer \(L+1\) reads \[ \delta_i = \rb{\delta_{i+1} A_{i+1}} \odot \phi_i'(z_i), \qquad i = L,\ldots,1. \] a. Specify the dimensions of \(\delta_i\), \(\delta_{i+1}\), \(A_{i+1}\), \(z_i\) and \(\phi_i'(z_i)\). b. Check that both products are well-defined. c. What do these dimensions become in the first step, \(i=L\)?
Solution
Solution, for real
There is one \(\delta\) per neuron, so \(\delta_i\in\R^{q_i}\) and \(\delta_{i+1}\in\R^{q_{i+1}}\). The weight matrix of layer \(i+1\) maps the hidden vector \(h_i\in\R^{q_i}\) to the pre-activation \(z_{i+1}\in\R^{q_{i+1}}\), so \(A_{i+1}\in\R^{q_{i+1}\times q_i}\). Also \(z_i\in\R^{q_i}\), and since \(\phi_i\) is applied element-wise, \(\phi_i'(z_i)\in\R^{q_i}\).
The product \(\delta_{i+1}A_{i+1}\) therefore reads \(\delta_{i+1}\) as a row vector of shape \(1\times q_{i+1}\), and \(\rb{1\times q_{i+1}}\cdot \rb{q_{i+1}\times q_i}\) has shape \(1\times q_i\), i.e. a vector in \(\R^{q_i}\). The Hadamard product multiplies two vectors of \(\R^{q_i}\) element-wise, so the right-hand side lies in \(\R^{q_i}\), which matches \(\delta_i\).
In the first step \(i=L\), the output layer has one neuron, \(q_{L+1}=1\). Hence \(\delta_{L+1}\) is a scalar and \(A_{L+1}\in\R^{1\times q_L}\), so \(\delta_{L+1}A_{L+1}\in\R^{q_L}\) is the row of output weights scaled by the output error.