4 Trees, Bags, and Random Forests
Instead of paying for a route planner such as Komoot,1A mobile app for
navigation and route planning,
Wikipedia: Komoot. why not try to
build our own? OpenStreetMap (OSM) offers map data. From this we can get edges and
features of edges such as highway classification (path, track, primary
road, \ldots), surface (sand, asphalt, gravel, \ldots), and access
restrictions. Binary features indicate whether an edge lies in a protected area
or crosses a bridge or tunnel. We also compute spatial features
ourselves, for instance the distance to the nearest forest, water, or motorway.
Then we need labeled edges that tell us whether an edge is good (0) or bad (1).
We label edges in published walks such as the Pieterpad as good. We call an edge bad if it lies in an industrial zone or
next to a motorway. With these labeled edges, we can train a classifier that can
score new, unlabeled edges. We convert these scores into edge costs, find a
minimum-cost path from a point \(A\) where we want to start our walk to the
finish \(B\), and plot it on a map. In this chapter we show how to set up a
classifier for our map, which contains about \(10^7\) edges.
A binary decision tree can score an edge by asking yes/no questions about its features: is the highway type a major road? is the distance to the nearest forest below 100 m? is the surface paved? Each answer selects a branch. At a leaf, the tree returns the fraction of training edges in that leaf labeled bad. For our walking app, this fraction lies in \([0, 1]\) by construction.
In slightly more abstract terms,2Wikipedia: Decision tree learning. a tree maps a feature vector \(x\) to a prediction \(\hat a=T(x)\). Each internal node stores a split rule and two child nodes; each leaf stores a prediction.
A single tree is easy to interpret, but deep trees can be unstable: small changes in the training data can change their splits and predictions. This is high variance. Bagging, random forests, and boosting are useful ensemble methods that combine trees to reduce this instability.
4.1 Decision trees
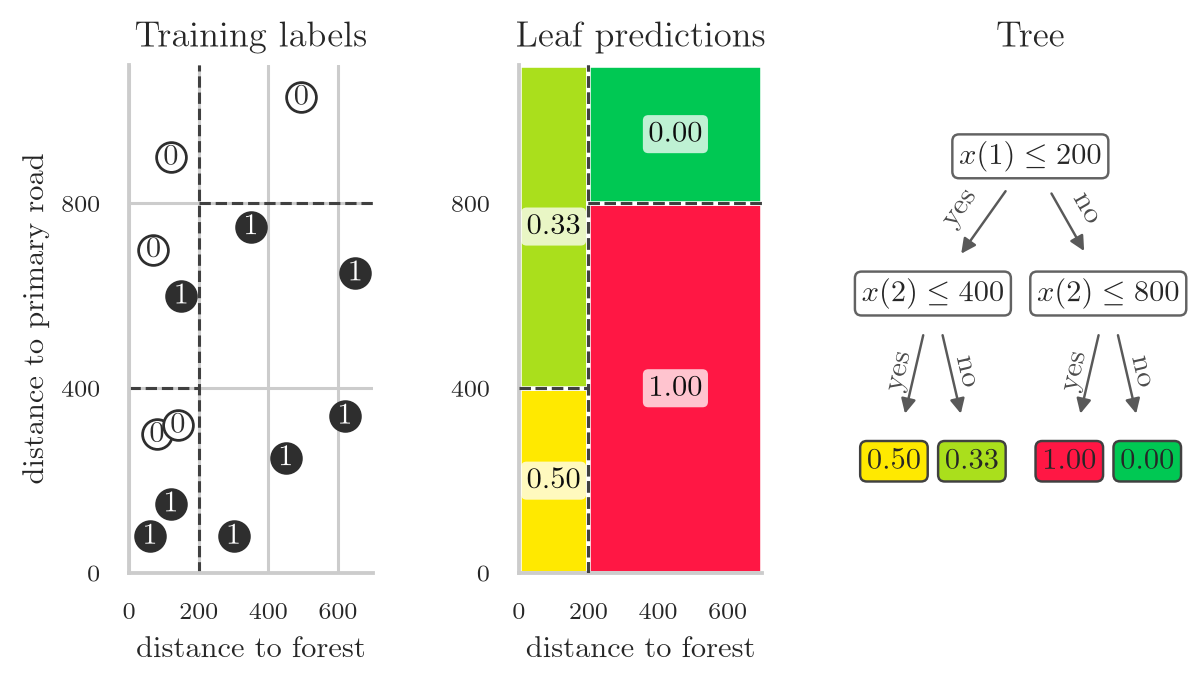
Consider two features: distance to a forest, \(x(1)\), and distance to a
primary
road
, \(x(2)\), both in meters.3For the real app, we use many more
features. The left panel in
Fig. 4.1 shows a few edges that have been labeled:
\(y=0\) means that the edge is a good edge, and \(y=1\) means that it is a bad
edge. We place the labels in the figure such that \(x(1)\) measures
dist_to_forest and \(x(2)\) measures dist_to_primary_road, both in meters.
If we use \(200\) to split on the distance to forest, and then use \(400\) or
\(800\) for the primary road on the left or right branch respectively, the
splits place 4 samples in the lower-left rectangle. Their
mean label is \(0.5\), which becomes the leaf prediction. The tree predicts an
estimated probability \(0.5\) for an edge routed to this rectangle. For
the new edge \(x_{\mathrm{new}}=(60,700)\), the tree follows the left branch
and then the right branch, reaching the leaf with prediction \(0.33\). The right
panel shows this traversal.
Fitting a tree means choosing its splits and leaf predictions to minimize training risk. A leaf gives a constant prediction \(c\) to every sample that reaches it, so the quantities we need are exactly those of Chapter 3: the empirical risk \(\hat R_{\Sset}(c)\) of using \(c\) throughout a list \(\Sset\) of samples, the best such constant \(\hat c(\Sset)\), and the risk \(\hat R_{\Sset}(\hat c(\Sset))\) that it attains. For short, write \[ \hat R(\Sset) = \hat R_{\Sset}(\hat c(\Sset)). \] For regression, these are given by (3.2.3), while for classification we use .
The leaves of a fitted tree form a partition \(\Pset_{\Tset}(T) = \set{\Tset_1, \ldots, \Tset_m}\) of the training set \(\Tset\) such that \(\Tset_{t}\) is the list of samples belonging to a leaf \(t\). The training risk of \(T\) is therefore4Recall, on a leaf \(\hat c(\Tset_{t})\) is constant.
\begin{align*} \hat R_{\Tset}(T) = \frac{1}{|\Tset|} \sum_{t=1}^{m} \sum_{(x,y)\in \Tset_{t}} \lscr(r(y), \hat c(\Tset_{t})) = \frac{1}{|\Tset|} \sum_{t=1}^{m} |\Tset_{t}|\, \hat R(\Tset_{t}). \tag{4.1.1} \end{align*}The training goal can now be stated as an optimization problem5The summation runs over all leaves \(\Sset\) of the tree \(T\) that form the partition of \(\Tset\).
\begin{align*} \min_{T\in \Fset} \sum_{\Sset\in \Pset_{\Tset}(T)} \frac{|\Sset|}{|\Tset|}\, \hat R(\Sset), \tag{4.1.2} \end{align*}where the model class \(\Fset\) is the set of all trees of a given maximal depth.
In general the best tree by exhaustive search is impossible because the number of candidate trees grows rapidly with depth. Let us estimate that growth.
For a binary tree we use a feature coordinate to split the \(n\) samples into a left set with \(l\) elements and a right set with \(n-l\) elements. Assuming distinct feature values, the number of candidate splits at this node is \((n-1)p\).6We can use each of the \(p\) features to split, and then split between any of the \(n\) samples. . Assume the root node has depth at most \(h\).7That is, the number of decisions until reaching a leaf node. Then the number of trees \(N_h(n)\) when the depth is \(h\) and the number of samples is \(n\) satisfies the recursion
\begin{align*} N_h(n) &= p \sum_{l=1}^{n-1} N_{h-1}(l)\,N_{h-1}(n-l), & N_{0}(n) &= 1; \end{align*}when \(h=0\) we stop splitting so there is just one tree left. Suppose \(N_h(n)\sim n^{u_h}p^{v_h}\). Matching the exponents of \(p\) in the above master equation gives
\begin{align*} v_{h} &= 1 + 2 v_{h-1}, & v_{0} &= 0, &\implies v_{h} = 2^{h} -1. \end{align*}For \(u_h\), we should solve
\begin{align*} n^{u_{h}} = \sum_{l=1}^{n-1} l^{u_{h-1}} (n-l)^{u_{h-1}}. \end{align*}Approximating the sum by an integral,
\begin{align*} \sum_{l=1}^{n-1} l^{u} (n-l)^{u}= n^{2u}\sum_{l=1}^{n-1} \rb{\frac{l}{n}}^{u} \rb{1-\frac{l}{n}}^{u} \simeq n^{2u+1} \int_{0}^{1} x^{u}(1-x)^{u} \d x. \end{align*}The (beta) integral does not depend on \(n\). So, again matching exponents in the master equation gives
\begin{align*} u_{h} &= 1 + 2 u_{h-1}, & u_{0} &= 0, &\implies u_{h} = 2^{h} -1. \end{align*}Therefore, the rough growth estimate for the number of trees with at most \(h\) levels of splits is
\begin{align*} N_{h}(n) \sim (n\,p)^{2^{h}-1}. \end{align*}For our case, \(n\approx 10^5\), \(p=30\), and \(h=5\), this is about \(10^{200}\).
Greedy splitting is the customary way around the search over all possible trees in (4.1.2). Suppose the current subtree is to be fitted on \(\Tset\). Then we compare two options: make the current node a leaf, or split \(\Tset\) into a left part \(\Lset\) and a right part \(\Rset\) and assume that each part becomes a leaf. The risk for the first option is \(\hat R(\Tset)\), that of the second is
\begin{align*} \frac{|\Lset|}{|\Tset|}\, \hat R(\Lset) + \frac{|\Rset|}{|\Tset|}\, \hat R(\Rset). \tag{4.1.3} \end{align*}If we can split \(\Tset\) such that the risk of the second option is smaller than that of the first, we should split and fit left and right subtrees on their respective parts. By recursion, the risk of the left branch is \(\hat R(\Lset)\), or smaller if it is better to split \(\Lset\) too. Since the argument also holds for \(\Rset\), we obtain \(\hat R_{\Tset}(T) \leq \hat R(\Tset)\).
The task is therefore to find the split that minimizes the risk for the second option. For each feature \(j\), try thresholds at its observed values. A threshold \(\theta\) sends \(z\) left when \(z(j)\leq\theta\), and right otherwise. Keep the split with the lowest weighted leaf risk, provided it improves on leaving the node unsplit. If none does, return \cn{Nil}. The threshold can instead be placed at a midpoint between consecutive distinct feature values.8This gives the same partition of the training samples.
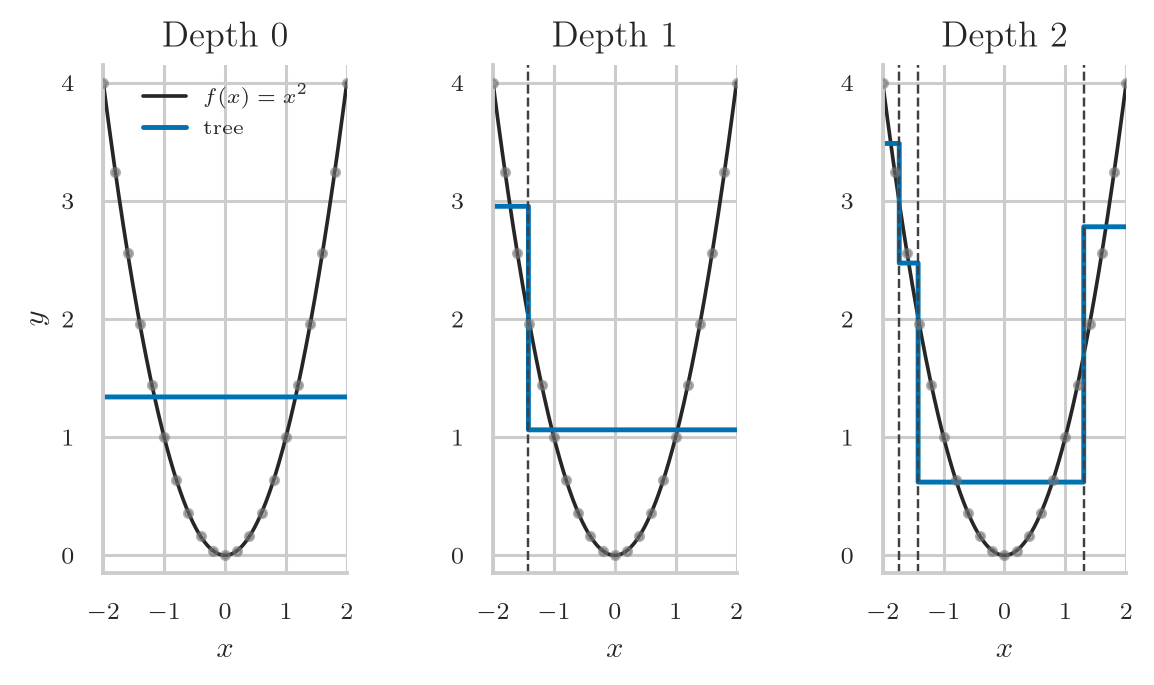
The \cl{Tree} class is implemented in Alg. 4.1.1. The constructor takes a maximum depth and a minimum split size \(\var{min\_elements}\).9These are the tree’s hyperparameters. A node becomes a leaf when its remaining depth is zero or it contains fewer than \(\var{min\_elements}\) samples. Each child receives one less unit of remaining depth. This minimum split size does not prevent a split from producing a singleton leaf. In Fig. 4.1, the initial tree has depth 2, and the leaf node for the lower-left rectangle has depth 0. The effect of the depth parameter is illustrated in Fig. 4.2, where regression trees of depth 0, 1, and 2 are fitted to the function \(f(x)=x^{2}\) on \([-2,2]\).
\begin{algorithm}
\caption{A binary tree class.}
\begin{algorithmic}
\State \textbf{Input:} the maximum depth and the minimum number of samples required to split a node.
\State \textbf{Output:} a tree with fit and predict methods.
\State \textbf{class } $\cl{Tree}(\var{depth}, \var{min\_elements})$
\State $\quad$ \textbf{instance variables:}
\State $\quad\quad \var{left\_tree} \gets \cn{Nil}$
\State $\quad\quad \var{right\_tree} \gets \cn{Nil}$
\State $\quad\quad \var{leaf?} \gets \cn{False}$ \Comment{Is this node a leaf?}
\State $\quad\quad \var{prediction} \gets \cn{Nil}$ \Comment{The prediction when the node is a leaf.}
\State $\quad$ \textbf{methods:}
\State $\quad\quad \pr{Predict}(x)$ \Comment{Return the prediction for the feature vector $x$.}
\State $\quad\quad \pr{Fit}(\Tset)$ \Comment{Fit the tree on a training set $\Tset$.}
\State $\quad\quad \pr{ChooseBranch}(x) \gets \cn{Nil}$ \Comment{Is $x$ in the left or right subtree?}
\end{algorithmic}
\end{algorithm}
Alg. 4.1.2 shows how to set up and use a \cl{Tree} for the example in Fig. 4.1. As in Chapter 3, the training data form a list \(\Tset\) of observations \((x,y)\). Here \(x\) is the feature vector of an edge and \(y\) is its observed label. Once fitted, the tree can return a numerical prediction for a feature vector \(x\) by asking a short sequence of questions about each feature coordinate \(x(j)\).
\begin{algorithm}
\caption{Fit a tree on the training data \Tset of Fig. 4.1, then compute a prediction.}
\begin{algorithmic}
\State $\var{tree} \gets \pr{Tree}(\var{depth} = 2, \var{min\_elements} = 5)$
\State $\var{tree}.\pr{Fit}(\Tset)$ \Comment{Fit the tree on the training set.}
\State $\var{x} \gets [60,700]$
\State $\var{prediction} \gets \var{tree}.\pr{Predict}(\var{x})$  \Comment{Returns the prediction 0.33.}
\end{algorithmic}
\end{algorithm}
The function \pr{Tree.Predict} returns \(\hat a = T(x)\) for a feature vector \(x\), see Alg. 4.1.3. If the current node is a leaf, i.e., when the member variable \var{leaf?} is \cn{True},[fn:: Read \var{leaf?} like a question: is this a leaf? More generally, any function or variable with a question mark should be read like “Is this …?”.} the method returns the member variable \var{prediction}.10\var{leaf?} and \var{prediction} are set by \pr{Tree.Fit}. The leaf node in Fig. 4.1 corresponding to the lower-left rectangle has prediction \(0.5\). If the current node is not a leaf, the function \pr{ChooseBranch} delegates the prediction to the left or right subtree.11Note, each tree has its own private \pr{ChooseBranch} function.
\begin{algorithm}
\caption{Predict for a feature vector \(x\) using the fitted tree.}
\begin{algorithmic}
\State \textbf{Input:} a feature vector $x$
\State \textbf{Output:} a prediction
\Procedure{Tree.Predict}{$x$}
    \If{$\var{leaf?}$}
        \Return $\var{prediction}$
    \EndIf
    \If{$\pr{ChooseBranch}(x) = \cn{Left}$}
        \Return $\var{left\_tree}.\pr{Predict}(x)$
    \EndIf
    \Return $\var{right\_tree}.\pr{Predict}(x)$
\EndProcedure
\end{algorithmic}
\end{algorithm}
\begin{algorithm}
\caption{Find the best split rule for a training set \(\Tset\).}
\begin{algorithmic}[1]
\State \textbf{Input:} a non-empty training set $\Tset$.
\State \textbf{Output:} a split rule, or $\cn{Nil}$ if no split into two non-empty parts lowers the training risk
\Procedure{BestSplitRule}{$\Tset$}
    \State $\var{min\_risk} \gets \hat R(\Tset)$ \Comment{Risk if the node becomes a leaf.}
    \State $\var{best\_rule} \gets \cn{Nil}$
    \For{$1\leq j \leq p$} \Comment{Loop over the feature coordinates}
        \For{$(x, y) \in \Tset$} \Comment{Loop over the training samples}
            \State $\theta \gets x(j)$  \Comment{Value of feature coordinate $j$ of this sample}
            \State $\pr{ChooseBranch} \gets \lambda: z \mapsto \cn{Left} \text{ if } z(j) \leq \theta \text{ else } \cn{Right}$
            \State $\Lset \gets \qb{(u, v) \in \Tset : \pr{ChooseBranch}(u) = \cn{Left}}$
            \State $\Rset \gets \qb{(u, v) \in \Tset : \pr{ChooseBranch}(u) = \cn{Right}}$
            \If{$|\Lset| > 0 \text{ and } |\Rset| > 0$}
                \State $\var{risk} \gets \frac{|\Lset|}{|\Tset|}\,\hat R(\Lset) + \frac{|\Rset|}{|\Tset|}\,\hat R(\Rset)$
                \If{$\var{risk} < \var{min\_risk}$}
                    \State $\var{min\_risk} \gets \var{risk}$
                    \State $\var{best\_rule} \gets \pr{ChooseBranch}$
                \EndIf
    \EndIf
        \EndFor
    \EndFor
    \Return $\var{best\_rule}$
\EndProcedure
\end{algorithmic}
\end{algorithm}
This implementation takes \(O(n^2p)\) time: it tries \(np\) thresholds and scans all \(n\) samples for each.
\pr{Tree.Fit} uses recursion to fit the tree, see Alg. 4.1.5.12In this pseudocode, \pr{Fit} is called once on a newly constructed object. If a stopping condition holds, Fit stores a leaf prediction. Otherwise, it finds the best split and fits each child on the samples sent to it. Each child receives one less unit of remaining depth, so a stopping condition is eventually reached. \pr{SetPrediction}(\Tset) returns the sample mean \(\hat c = \hat y = \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}y\) for recursion, and the class frequencies \(\hat c_{p} = |\qb{(x,y)\in\Tset:y=k}|/|\Tset|\).
\begin{algorithm}
\caption{Fit a tree recursively to a training set \(\Tset\).}
\begin{algorithmic}[1]
\State \textbf{Input:} a non-empty training set $\Tset$.
\State \textbf{Output:} none
\Procedure{Tree.Fit}{$\Tset$}
    \If{$\pr{StopSplitting?}(\Tset, \var{depth}, \var{min\_elements})$}
        \State $\var{leaf?} \gets \cn{True}$
        \State $\var{prediction} \gets \pr{SetPrediction}(\Tset)$
        \Return
    \EndIf
    \State $\pr{ChooseBranch} \gets \pr{BestSplitRule}(\Tset)$
    \State $\var{left\_tree} \gets \pr{Tree}(\var{depth} - 1, \var{min\_elements})$
    \State $\var{left\_tree}.\pr{Fit}(\qb{(x,y) \in \Tset : \pr{ChooseBranch}(x) = \cn{Left}})$
    \State $\var{right\_tree} \gets \pr{Tree}(\var{depth} - 1, \var{min\_elements})$
    \State $\var{right\_tree}.\pr{Fit}(\qb{(x,y) \in \Tset : \pr{ChooseBranch}(x) = \cn{Right}})$
\EndProcedure
\end{algorithmic}
\end{algorithm}
\pr{StopSplitting?}, see Alg. 4.1.6, tells the current node whether to stop or continue splitting. When \(\var{depth}=0\) or the training set becomes too small, the node must become a leaf. It can also happen that \pr{BestSplitRule} returns \cn{Nil} to indicate that there is no good split. Then the node must also become a leaf.13Compute the best split once and reuse it.
\begin{algorithm}
\caption{Decide whether the node should become a leaf.}
\begin{algorithmic}
\State \textbf{Input:} a non-empty training set $\Tset$, a depth, and a minimal split size.
\State \textbf{Output:} a Boolean.
\Procedure{StopSplitting?}{$\Tset, \var{depth}, \var{min\_elements}$}
    \If{$\var{depth} = 0$}
        \Return $\cn{True}$
    \EndIf
    \If{$|\Tset| < \var{min\_elements}$}
        \Return $\cn{True}$
    \EndIf
    \If{$\pr{BestSplitRule}(\Tset) = \cn{Nil}$}
        \Return $\cn{True}$
    \EndIf
    \Return $\cn{False}$
\EndProcedure
\end{algorithmic}
\end{algorithm}
4.2 Bags
Bagging reduces the variability of deep trees by averaging predictions from trees fitted to bootstrap samples. The name is short for bootstrap aggregating.14[[https://en.wikipedia.org/wiki/Bootstrap_aggregating][Wikipedia: Bootstrap aggregating].]
From the training set we draw a bootstrap sample: a new list formed by sampling \(n\) samples from \(\Tset\) with replacement. We grow one tree on each such bootstrap sample and aggregate their predictions.
Why resample rather than simply cut \(\Tset\) into as many parts as we want trees? Partitioning the data into \(B\) parts leaves each tree only \(n/B\) observations. Bootstrap samples overlap and retain much more of the training data for each tree. This can weaken each tree.
\pr{Bootstrap} draws \(|\Sset|\) elements from \(\Sset\) with replacement.
\begin{algorithm}
\caption{Make a bootstrap sample of a list \(\Sset\).}
\begin{algorithmic}
\State \textbf{Input:} a list $\Sset$.
\State \textbf{Output:} a list with $|\Sset|$ elements randomly selected with replacement from $\Sset$.
\Procedure{Bootstrap}{$\Sset$}
    \Return $\pr{SampleWithReplacement}(\Sset, |\Sset|)$
\EndProcedure
\end{algorithmic}
\end{algorithm}
Alg. 4.2.2 stores the fitted trees and their bootstrap indices. Its constructor takes the tree parameters and the number of trees.
\begin{algorithm}
\caption{A bag of binary decision trees.}
\begin{algorithmic}
\State \textbf{Input:} the number of trees in the bag, and the maximal depth and minimal split size of each tree.
\State \textbf{Output:} a bag with fit and predict methods.
\State \textbf{class } $\cl{Bag}(\var{num\_trees}, \var{depth}, \var{min\_elements})$
\State $\quad$ \textbf{instance variables:}
\State $\quad\quad \Bset \gets \qb{}$ \Comment{The list of (tree, index list) pairs.}
\State $\quad$ \textbf{methods:}
\State $\quad\quad \pr{Fit}(\Tset)$ \Comment{Fit the bag on a training set $\Tset$.}
\State $\quad\quad \pr{Predict}(x)$ \Comment{Return a prediction for the feature vector $x$.}
\State $\quad\quad \pr{OobPredict}(i)$ \Comment{Predict sample $i$ with the trees that did not see it.}
\State $\quad\quad \pr{OobRisk}(\Tset)$ \Comment{Return the out-of-bag risk.}
\end{algorithmic}
\end{algorithm}
The bag uses Alg. 4.2.3 to predict by letting every tree in the bag compute a prediction for the feature vector \(x\), and then averaging the results. Each element of \(\Bset\) is a pair \((T, \Iset)\) where \(\Iset\) is the list of indices the tree \(T\) was fitted on. The index list is not used in the prediction; we need it only for the out-of-bag risk below.
\begin{algorithm}
\caption{Predict for a feature vector \(x\) using the fitted bag.}
\begin{algorithmic}
\State \textbf{Input:} a feature vector $x$
\State \textbf{Output:} a prediction
\Procedure{Bag.Predict}{$x$}
    \Return $\pr{Average}(\qb{T.\pr{Predict}(x) : (T, \Iset) \in \Bset})$
\EndProcedure
\end{algorithmic}
\end{algorithm}
Alg. 4.2.4 grows the bag one tree at a time. For each tree, draw \(n\) training indices with replacement, fit the tree to those observations, and store both the tree and its index list. Different bootstrap samples can produce different trees.
\begin{algorithm}
\caption{Fit a bag to a training set \(\Tset\).}
\begin{algorithmic}
\State \textbf{Input:} a non-empty training set $\Tset$
\State \textbf{Output:} none
\Procedure{Bag.Fit}{$\Tset$}
    \While{$|\Bset| < \var{num\_trees}$}
        \State $\Iset \gets \pr{Bootstrap}(\qb{1,\ldots,n})$
        \State $T \gets \cl{Tree}(\var{depth}, \var{min\_elements})$
        \State $T.\pr{Fit}(\qb{(x_i, y_i) : i \in \Iset})$
        \State $\Bset \gets \Bset + \qb{(T, \Iset)}$
    \EndWhile
\EndProcedure
\end{algorithmic}
\end{algorithm}
The trees of a bag are usually grown deep: the averaging controls the variance that depth introduces, so each tree may fit its own bootstrap sample closely. In practice this means barely restricting the recursion at all. Rather than choosing a \(\var{depth}\), one drops the depth test of Alg. 4.1.6 and keeps the other two: the node becomes a leaf when it holds fewer than \(\var{min\_elements}\) samples, with \(\var{min\_elements}\) set to a small number, or when \pr{BestSplitRule} finds no split that lowers \(\hat R(\Tset)\).
Out-of-bag validation lets us tune the bag without a separate validation set. Call the \(b\)-th tree out-of-bag for sample \(i\) when \(i \notin \Iset_{b}\), that is, when the tree was not fitted on that sample. This happens with probability \(\rb{1-1/n}^{n}\), which tends to \(e^{-1}\approx 0.37\) as \(n\) grows.15One draw picks sample \(i\) with probability \(1/n\), hence misses it with probability \(1-1/n\). The draws are independent, so \(m\) draws all miss it with probability \(\rb{1-1/n}^{m}\). A bootstrap has as many draws as \(\Tset\) has samples, so \(m=n\). About a third of the trees are therefore out-of-bag for sample \(i\), and their average prediction for it can be compared with \(y_i\) without setting any data aside. Thus, we can use this risk to select the hyperparameters of the bag. Afterward, reserve untouched test data for final assessment.
Two elements of the bag serve this purpose. First, a tree must know which samples it did not train on, which is why Alg. 4.2.4 stores the index list \(\Iset_{b}\) next to the tree. Second, the bag needs a prediction method of its own: Alg. 4.2.3 averages over all trees, and using it here would evaluate each tree on data it was fitted on. Alg. 4.2.5 therefore averages over the out-of-bag trees only, and Alg. 4.2.6 compares those averages with the labels. We state the risk for regression. The bag retains the training data, so \pr{OobPredict} can retrieve \(x_i\) from the input index \(i\).
\begin{algorithm}
\caption{Out-of-bag prediction for sample \(i\).}
\begin{algorithmic}
\State \textbf{Input:} an index $i$.
\State \textbf{Output:} a prediction for sample $i$.
\Procedure{Bag.OobPredict}{$i$}
    \State $\Vset \gets \qb{T : (T, \Iset) \in \Bset, i \notin \Iset}$
    \Comment{The trees that are out-of-bag for sample $i$.}
    \If{$\Vset = \qb{}$}
        \Return $\cn{Nil}$
    \EndIf
    \Return $\pr{Average}(\qb{T.\pr{Predict}(x_i) : T \in \Vset})$
\EndProcedure
\end{algorithmic}
\end{algorithm}
\begin{algorithm}
\caption{The out-of-bag risk of the bag; the regression case.}
\begin{algorithmic}[1]
\State \textbf{Input:} the training set $\Tset$ the bag was fitted on.
\State \textbf{Output:} the out-of-bag risk.
\Procedure{Bag.OobRisk}{$\Tset$}
    \State $\Wset \gets \qb{}$
    \For{$1 \leq i \leq n$}
        \State $\hat y \gets \pr{Bag.OobPredict}(i)$
        \If{$\hat y \neq \cn{Nil}$}
            \State $\Wset \gets \Wset + \qb{(\hat y - y_i)^{2}}$
        \EndIf
    \EndFor
    \If{$\Wset = \qb{}$}
        \Return $\cn{Nil}$
    \EndIf
    \Return $\pr{Average}(\Wset)$
\EndProcedure
\end{algorithmic}
\end{algorithm}
The \(\cn{Nil}\) case occurs when sample \(i\) was drawn into every bootstrap, so that no tree is out-of-bag for it. Such samples are skipped so that the average runs only over the samples that have at least one out-of-bag tree. If all samples are skipped, \pr{OobRisk} returns \(\cn{Nil}\).16A given sample has no out-of-bag tree with probability \(\rb{1-\rb{1-1/n}^{n}}^{B}\approx 0.63^{B}\), which is about \(10^{-4}\) for \(B=20\) trees.
The remaining hyperparameter \(\var{num\_trees}\) is not chosen this way, since (4.2.1) below shows that the variance decreases in the number of trees; we take as many trees as we can afford to compute.
The variance of a bag has an interesting form. For a fixed training set \(\Tset\) Alg. 4.2.4 draws for the \(b\)-th pass of the loop a bootstrapped index list \(\Iset_{b} = (I_{b,1}, \ldots, I_{b,n})\), and then Alg. 4.1.5 fits a deterministic tree on the samples \(\qb{(x_{i}, y_{i}) : i \in \Iset_{b}}\). Hence, there is a function \(h\) such that \(T_{b} = h(\Iset_{b}, \Tset)\) is a predictor function.
Lemma 4.2.1.
Conditional on \(\Tset\), the predictors \(T_{1}, \ldots, T_{B}\) are iid.
Proof
Condition on \(\Tset\), so that \(h(\cdot, \Tset)\) is a fixed function. The index lists \(\Iset_{1}, \ldots, \Iset_{B}\) are independent and identically distributed, each consisting of \(n\) uniform draws on \(\set{1,\ldots,n}\). Measurable functions of independent random variables are independent, hence so are the \(T_{b} = h(\Iset_{b}, \Tset)\), \(b=1,\ldots,B\), and they are identically distributed because the \(\Iset_{b}\) are.
For a new observation \(X\) the bag predicts the average
\begin{align*} \bar T(X) = \frac{1}{B}\sum_{b=1}^{B} T_{b}(X). \end{align*}We can use Eve’s law to split the variance into
\begin{align*} \V{\bar T(X)} = \E{\V{\frac{1}{B}\sum_{b=1}^{B} T_{b}(X) \given \Tset}} +\V{\E{\frac{1}{B}\sum_{b=1}^{B} T_{b}(X) \given \Tset}}. \end{align*}With respect to the right most term:17Here we pick the first, but any of the trees would do.
\begin{align*} \E{\frac{1}{B}\sum_{b=1}^{B} T_{b}(X) \given \Tset} = \E{T_{1}(X) \mid \Tset}, \end{align*}because the \(T_b\) are identically distributed as \(T_1\). For the other term, we use that the \(T_b\) are iid conditional on \(\Tset\),
\begin{align*} \V{\frac{1}{B}\sum_{b=1}^{B} T_{b}(X) \given \Tset} = \frac{1}{B^{2}} \sum_{b=1}^{B} \V{T_{b}(X)\given \Tset} = \frac{1}{B}\V{T_{1}(X)\given \Tset}. \end{align*}Thus, by increasing \(B\), the variance of the prediction of \(X\) becomes smaller. All in all
\begin{align*} \V{\bar T(X)} &= \frac{1}{B}\E{\V{T_{1}(X) \given \Tset}} + \V{\E{T_{1}(X) \given \Tset}.} \tag{4.2.1} \end{align*}Consequently, the variance of the expected prediction of \(T_1(X)\) due to fitting on samples of the training set cannot be removed by increasing the size of the bag.
We can rewrite the above in a slightly different way. By Eve’s law
\begin{align*} \V{T_{1}(X)} = \E{\V{T_{1}(X) \given \Tset}} + \V{\E{T_{1}(X) \given \Tset}}, \end{align*}so that
\begin{align*} \V{\bar T(X)} &= \frac{1}{B}\V{T_{1}(X)} + \frac{B-1}{B}\V{\E{T_{1}(X) \given \Tset}} \\ \end{align*}Next, two trees of one bag are identically distributed, so \(\V{T_{2}} = \V{T_{1}}\), and therefore the correlation can be written as
\begin{align*} \rho = \frac{\cov{T_{1}(X), T_{2}(X)}}{\sqrt{\V{T_{1(X)}}\V{T_{2(X)}}}} = \frac{\cov{T_{1}(X), T_{2}(X)}}{\V{T_{1}(X)}}. \end{align*}From the law of total covariance,18For random variables \(U\), \(V\) and \(W\), \(\cov{U,V} = \E{\cov{U,V\given W}} + \cov{\E{U\given W}, \E{V\given W}}\). With \(U=V\) this is the law of total variance.
\begin{align*} \cov{T_{1}(X), T_{2}(X)} = \E{\cov{T_{1}(X), T_{2}(X)\given\Tset}} + \cov{\E{T_{1}(X)\given\Tset}, \E{T_{2}(X)\given\Tset}}. \end{align*}Conditional independence makes the first term zero, and in the second both conditional expectations have the same distribution, hence,
\begin{align*} \cov{T_{1}(X), T_{2}(X)} = \V{\E{T_{1}(X)\given\Tset}}. \end{align*}And so,
\begin{align*} \rho &= \frac{\V{\E{T_{1}(X)\mid \Tset}}}{\V{T_{1}(X)}} &\implies \V{\E{T_{1}(X)\mid \Tset}} &= \rho {\V{T_{1}(X)}}. \end{align*}Substitution in the above expression for the variance gives
\begin{align*} \V{\bar T(X)} &= \rho \V{T_{1}(X)} + \frac{1-\rho}{B} \V{T_{1}(X)}. \end{align*}4.3 Random forests
A random forest19Wikipedia: Random forest. extends bagging with one further source of randomness. When one feature dominates, many bagged trees choose it for their first split. A random forest samples a subset of candidate features at each node.
The conceptual change in the code is small. Where a normal tree uses the full feature set in the feature loop of Alg. 4.1.4, a random forest only considers \(\var{num\_candidates}\) of them. We use Alg. A.0.9 \[ \pr{SampleWithoutReplacement}(\qb{1, \ldots, p}, \var{num\_candidates}) \] to select the features randomly. Common choices are \(\var{num\_candidates} = \sqrt{p}\) or \(\var{num\_candidates} = p/3\), rounded to the nearest integer. A forest is otherwise a bag: it grows \(\var{num\_trees}\) trees on bootstrap samples and averages them, and its out-of-bag risk is Alg. 4.2.6.
Using fewer candidate features can reduce correlation, but can also weaken the individual trees. Choose the number of candidates by out-of-bag risk. Using all \(p\) features recovers bagging.
4.4 Exercises
Consider a version of the first tree figure in which the text inside the tree nodes has been removed, while the tree structure, the arrows, and the ``yes’’/``no’’ labels remain visible.
Complete the tree by filling in the split rule at each internal node and the prediction at each leaf. Use the training labels and leaf regions shown in the figure. The left branch corresponds to ``yes’’ and the right branch to ``no’’.
Solution
Solution, for real
The completed tree is
The leaf predictions, from left to right, are
\[ 0.50,\qquad 0.33,\qquad 1.00,\qquad 0.00. \]
Complete the ??? part.
\begin{algorithm}
\begin{algorithmic}
\State \textbf{Input:} a feature vector $x$
\State \textbf{Output:} a prediction
\Procedure{Tree.Predict}{$x$}
    \If{$\var{leaf?}$}
        \Return $\var{prediction}$
    \EndIf
    \If{ ???? }
        \Return $\var{left\_tree}.\pr{Predict}(x)$
    \EndIf
    \Return $\var{right\_tree}.\pr{Predict}(x)$
\EndProcedure
\end{algorithmic}
\end{algorithm}
Solution
Solution, for real
The completed algorithm is given in Alg. 4.1.3.
Complete the ??? part.
\begin{algorithmic}[1] \State \textbf{Input:} a non-empty training set $\Tset$. \State \textbf{Output:} a split rule, or $\cn{Nil}$ if no split into two non-empty parts lowers the training risk \Procedure{BestSplitRule}{$\Tset$} \State $\var{min\_risk} \gets \hat R(\Tset)$ \Comment{Risk if the node becomes a leaf.} \State $\var{best\_rule} \gets \cn{Nil}$ \For{$1\leq j \leq p$} \Comment{Loop over the feature coordinates} \For{$(x, y) \in \Tset$} \Comment{Loop over the training samples} \State $\theta \gets x(j)$ \Comment{Value of feature coordinate $j$ of this sample} \State $\pr{ChooseBranch} \gets$ ???? \State $\Lset \gets \qb{(u, v) \in \Tset : \pr{ChooseBranch}(u) = \cn{Left}}$ \State $\Rset \gets \qb{(u, v) \in \Tset : \pr{ChooseBranch}(u) = \cn{Right}}$ \If{$|\Lset| > 0 \text{ and } |\Rset| > 0$} \State $\var{risk} \gets \frac{|\Lset|}{|\Tset|}\,\hat R(\Lset) + \frac{|\Rset|}{|\Tset|}\,\hat R(\Rset)$ \If{$\var{risk} < \var{min\_risk}$} \State $\var{min\_risk} \gets \var{risk}$ \State $\var{best\_rule} \gets \pr{ChooseBranch}$ \EndIf \EndIf \EndFor \EndFor \Return $\var{best\_rule}$ \EndProcedure \end{algorithmic}Solution
Solution, for real
The completed algorithm is given in Alg. 4.1.4.
Complete lines 5 and 6 of the \pr{Tree.Fit} algorithm.
\begin{algorithmic}[1] \State \textbf{Input:} a non-empty training set $\Tset$. \State \textbf{Output:} none \Procedure{Tree.Fit}{$\Tset$} \If{$\pr{StopSplitting?}(\Tset, \var{depth}, \var{min\_elements})$} \State ??? \State ??? \Return \EndIf \State $\pr{ChooseBranch} \gets \pr{BestSplitRule}(\Tset)$ \State $\var{left\_tree} \gets \pr{Tree}(\var{depth} - 1, \var{min\_elements})$ \State $\var{left\_tree}.\pr{Fit}(\qb{(x,y) \in \Tset : \pr{ChooseBranch}(x) = \cn{Left}})$ \State $\var{right\_tree} \gets \pr{Tree}(\var{depth} - 1, \var{min\_elements})$ \State $\var{right\_tree}.\pr{Fit}(\qb{(x,y) \in \Tset : \pr{ChooseBranch}(x) = \cn{Right}})$ \EndProcedure \end{algorithmic}Solution
Solution, for real
The completed algorithm is given in Alg. 4.1.5.
In Alg. 4.2.6, why does the algorithm test whether \(\hat y \neq \cn{Nil}\) before adding a loss to \(\Wset\)? Explain what `Nil` means in this context and why including such a case in the average would give an incorrect out-of-bag risk.
Solution
Solution, for real
For some sample \(i\), every tree in the bag may have used \(i\) in its bootstrap sample. Then there is no out-of-bag tree available to predict \(i\), so \(\pr{Bag.OobPredict}(i) = \cn{Nil}\). Such a sample has no valid out-of-bag loss and must be skipped. The risk is averaged only over samples with at least one out-of-bag prediction; if all samples are skipped, the algorithm returns \(\cn{Nil}\).
Random forests use random feature selection at each node. Which line in Alg. 4.1.4 must be changed to turn the split rule into the one used by a random forest, and how should it be changed?
Solution
Solution, for real
Change the feature loop
\[ \textbf{for } 1\leq j\leq p \]
to
\[ \textbf{for } j\in \pr{SampleWithoutReplacement}(\qb{1,\ldots,p},\var{num\_candidates}). \]
The sample of candidate features is drawn once for each invocation of `BestSplitRule`, hence once at each node, and the selected features are then used for all threshold candidates tested at that node.
Derive (4.2.1).
Solution
Solution, for real
In what sense is a random forest different from a bag? Why?